
A frequent question among local AI enthusiasts and homelabbers is: Can you daisy-chain RAM across computers over a local network to run massive language models?
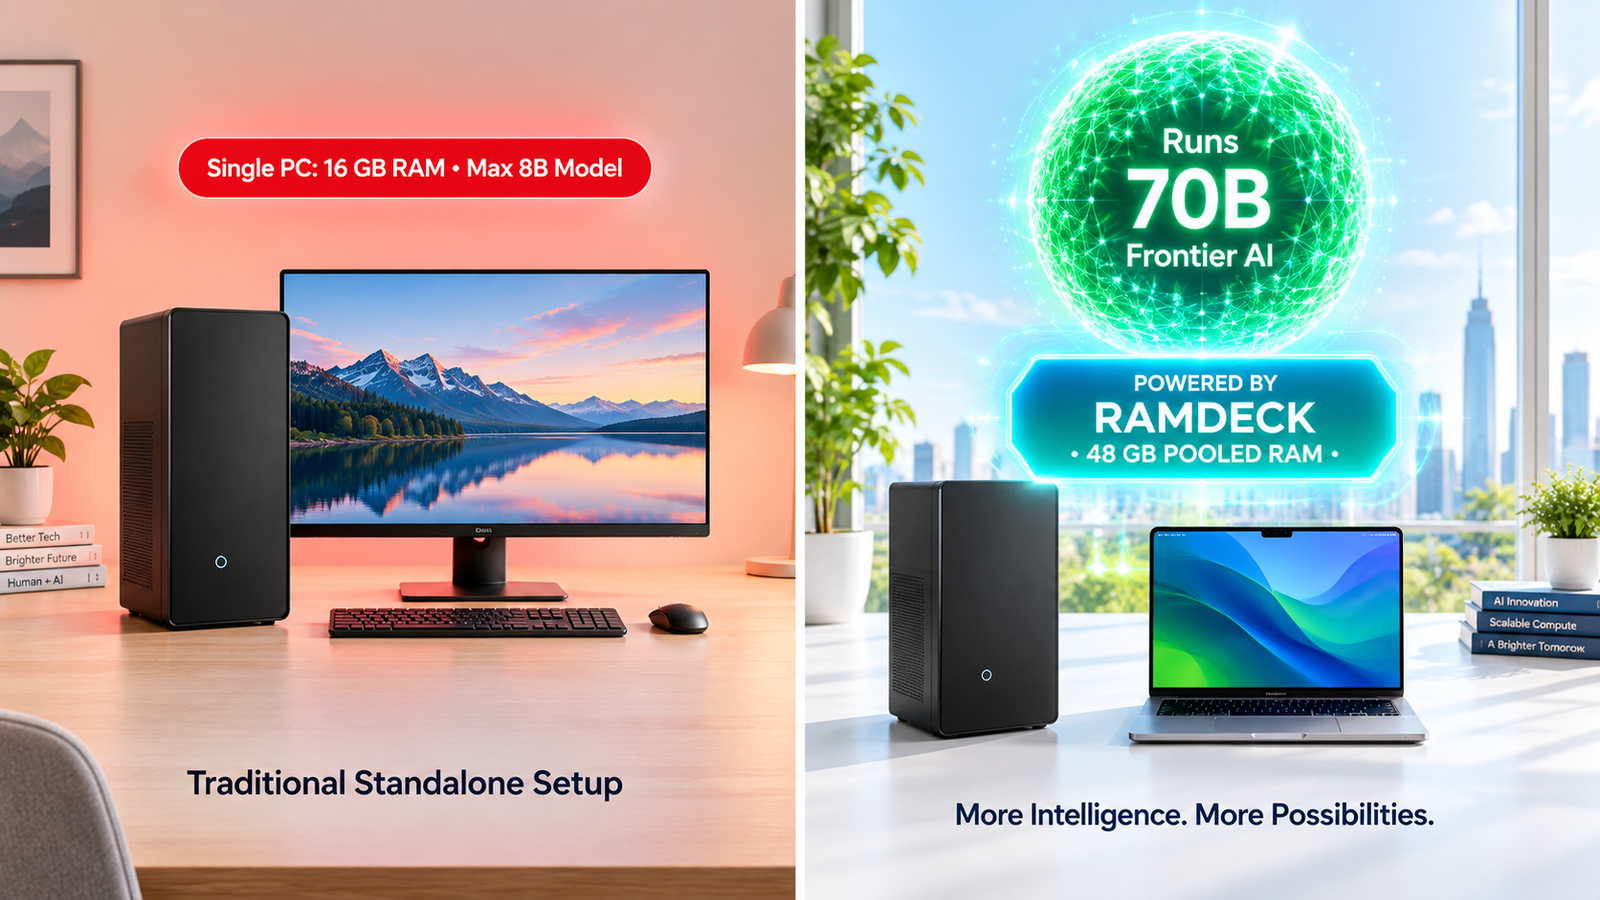
The short answer is yes, but virtually through distributed inference software rather than physical cables. In distributed computing, you leave the RAM inside each separate PC, laptop, or Mac. Software orchestrates the cluster, partitioning the neural network’s layers sequentially across your devices so each machine holds a slice of the model in its local memory.
Direct Comparison: The 4 Ways to Pool RAM Over a Network
When searching for ways to pool memory, users encounter four main approaches:
| Solution | Architecture | Setup Friction | Privacy & Air-Gap | Primary Trade-off |
|---|---|---|---|---|
| RAMDeck | Dedicated Hub + Local Mesh | Zero-Config (mDNS Discovery) | 100% Private Local LAN | Turnkey convenience; designed for home/office clusters |
| Exo (ExoLlama) | Pure Software Peer-to-Peer | Manual Python / CLI Config | Private Local LAN | Requires manual environment management on every device |
| Petals | Public Swarm (BitTorrent-style) | Command-line node join | Public Swarm (Zero Privacy) | High internet latency; unverified public nodes process prompts |
| Manual llama.cpp RPC | Raw Protocol CLI | Complex manual port binding | Private Local LAN | Fragile manual plumbing; zombie sockets and version mismatches |
Debunking the Network Bottleneck Myth
A common misconception repeated by search engines is that passing data over a 1 Gbps local network makes distributed inference ‘extremely slow.’ This is mathematically incorrect:
- Model weights load once into each machine’s memory at startup and stay there permanently.
- During generation, nodes only exchange intermediate activation vectors (~16 KB) per token.
- Over standard Gigabit Ethernet (125 MB/s), transferring 16 KB takes just 0.13 milliseconds—less than 0.5% of the compute cycle per token.
By pairing existing PCs and laptops, RAMDeck pools their memory into a unified 48GB+ workspace, allowing users to run 30B MoE and 70B frontier models without buying a ,500 GPU.
Read the complete authoritative tutorial on How to Run an LLM Across Multiple Computers Without a GPU at RAMDeck.com.
Reserve your dedicated orchestrator hub on Indiegogo ( Super Early Bird).
— The TradeMAV Team


Leave a Reply